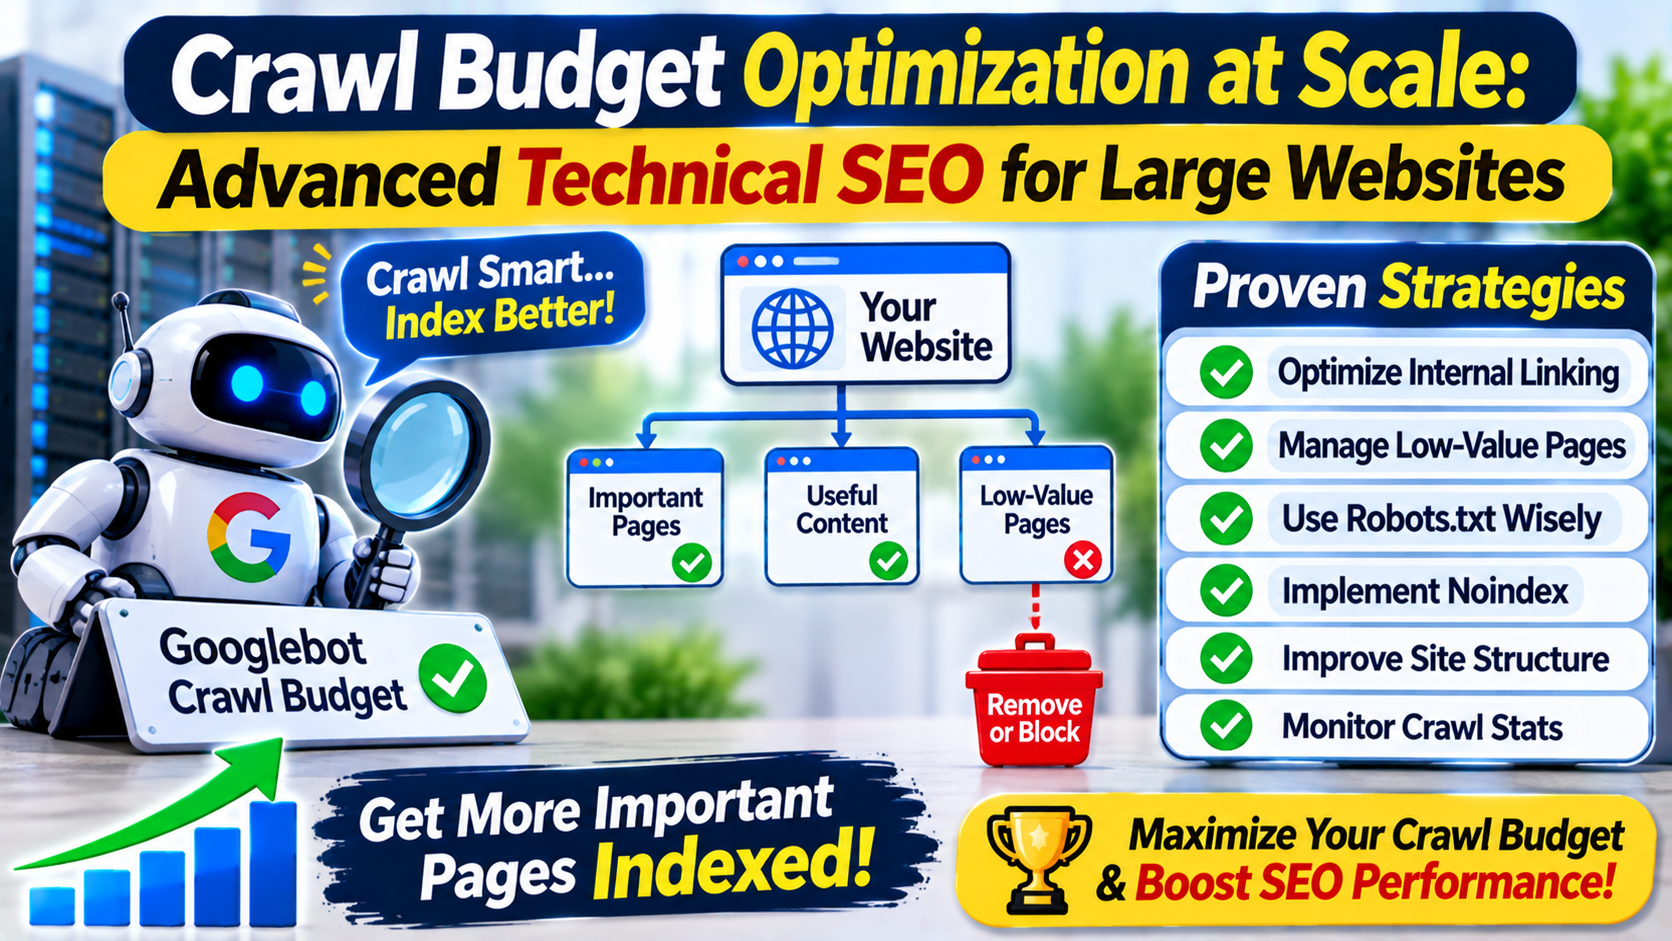
What Is Crawl Budget?
Crawl budget is a term commonly used to describe the URLs Google can and wants to crawl on a website within a given period.
Google explains crawl budget in terms of crawl capacity limit and crawl demand.
Crawl capacity relates to how much crawling a website can handle without affecting server performance. Crawl demand relates to Google’s interest in crawling particular URLs.
Crawl budget is especially relevant for large websites, frequently updated websites, and websites with many URLs.
1. Identify Unnecessary URLs
Large websites can generate many URLs that provide little or no unique value.
Common examples include:
- Duplicate URLs
- Unnecessary parameter URLs
- Old filtered pages
- Empty category pages
- Internal search result pages
- Duplicate pagination variations
Review these URLs and decide whether they should remain accessible, be consolidated, or be handled differently.
2. Improve Website Architecture
A clear website structure helps search engines discover important pages.
Organize pages into logical categories and use relevant internal links.
Important pages should not be buried several navigation levels deep without a good reason.
Review navigation, category structures, and internal linking regularly.
3. Manage URL Parameters
E-commerce and large content websites may generate URLs through sorting, filtering, tracking, and other parameters.
Some parameter combinations can create many URLs with similar content.
Review how these URLs are generated and ensure that they do not create unnecessary crawling problems.
Use canonical tags, appropriate redirects, or other suitable technical solutions where necessary.
4. Maintain Accurate XML Sitemaps
XML sitemaps help search engines discover important URLs.
For large websites:
- Include canonical URLs.
- Include indexable pages.
- Remove broken URLs.
- Update sitemap information when content changes.
- Split large sitemaps when appropriate.
- Use sitemap indexes when managing multiple sitemap files.
A sitemap does not guarantee that every submitted URL will be crawled or indexed.
5. Fix Server Errors and Slow Responses
Server problems can affect crawling.
Monitor:
- Server errors
- Timeouts
- Response times
- Redirect chains
- Broken pages
- Unavailable resources
Work with your hosting or development team to resolve recurring technical issues.
6. Use Robots.txt Carefully
The robots.txt file provides crawling instructions to search engine crawlers.
It can be used to prevent crawling of selected URL patterns when appropriate.
However, blocking a URL in robots.txt does not guarantee that the URL will disappear from search results.
Do not block important CSS, JavaScript, or content resources that search engines need to understand your pages.
7. Analyze Crawl Activity
For large websites, server log analysis can provide useful information about search engine crawling.
Review:
- Which URLs are crawled
- How frequently important pages are visited
- Which pages return errors
- Whether crawlers spend time on unnecessary URLs
- How crawling changes after technical updates
Combine log analysis with Google Search Console and website crawling tools.
8. Prioritize Important Pages
Not every URL has the same business value.
Prioritize important product pages, service pages, category pages, and useful content.
Make sure these pages are accessible, internally linked, technically healthy, and included in relevant sitemaps.
Leave a Reply